Mansi
HOMEWORKASKABOUTCONTACT
Resume

Home/Work

Project 03

Automated Web Intelligence Pipeline

A noise sieve — scattered sources become actionable reports.

Lead Data Engineer · Data Platforms · Cloud Architecture · ETL ModernizationData Engineering · Automation · AWS

PythonScrapySeleniumAWS LambdaAmazon S3EC2
Web intelligence pipelineRSS, generic, and site-specific crawlers merge into unique storage, then DS classification and reporting.SourcesExtractStoreClassifyReportStartSource linksRSS crawlerfeedparserGeneric crawlerSeleniumSite-specificantibot + scrapeExtract articlesUnique storededupeDS classifierrelevancyReportstakeholders
RSS, generic, and site-specific crawlers merge into unique storage, then DS classification and reporting.

01 — The problem

Relevant public web content was spread across inconsistent page structures and feeds; manual monitoring, extraction, and deduplication did not scale.

02 — The system

Select a layer to see its role.

Data flow

  1. 01Source discoveryRSS / Crawlers
  2. 02ExtractionScrapy / Selenium
  3. 03ProcessingNormalize / Deduplicate
  4. 04StorageAWS S3
  5. 05Model inferenceDS-owned classifier
  6. 06ReportingRelevant intelligence

Technology — why it was used

Python

Scrapy

Selenium

AWS Lambda

Amazon S3

EC2

Terraform

Bitbucket Pipelines

05 — Evidence
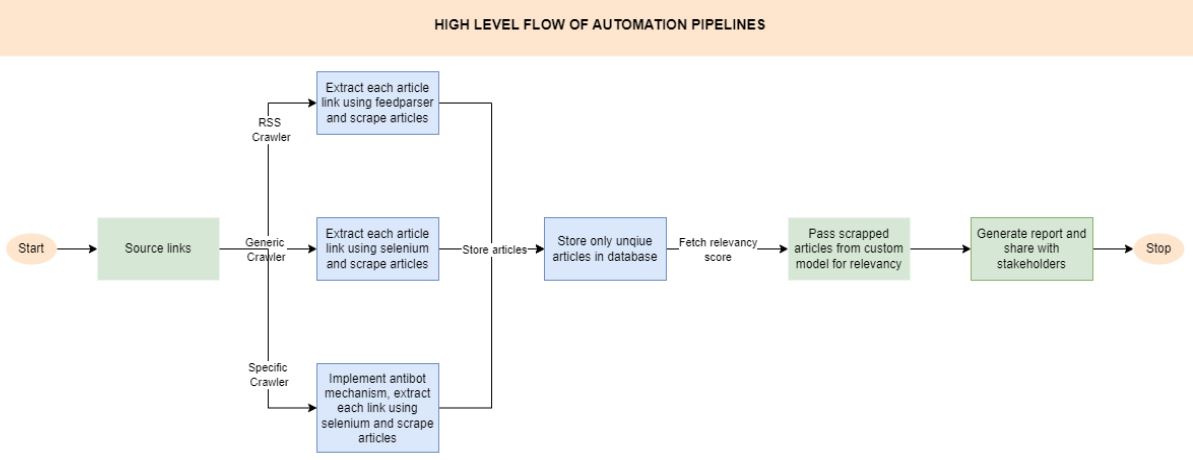
Discover → extract → process → integrate → report

Takeaway

Fragmented inputs need visible failure on schedule — not silent drift.

  • Engineering owns the production path; DS owns the classifier.

What landed

  • Delivered an automated intelligence workflow from web discovery through reporting
  • Connected engineering pipeline stages with DS-owned model inference
PreviousML-Driven Allocation EngineAll workNextOLAP → Workload-Specific Architecture
Mansi

© 2026 Mansi Dhruv. All rights reserved.

Created with curiosity